01Edge AI · Thesis · Two-person team
AI-poweredsearch & rescuesystem
From a camera in the air to the operator’s screen: a working human-detection system, tested in the field.
- On-device inference
- Jetson Nano · TensorRT FP16
- Selected model (validation)
- YOLOv11 · mAP@0.5 0.8694
- Stream to operator
- DeepStream · RTSP
- Field test
- Gazi University campus
My contribution
The system was built end to end by a team of two—from research and procurement to sponsorship and assembly. I was primarily responsible for the computer vision, dataset and model development, training and evaluation, camera selection and the Jetson-based edge AI pipeline. The project was supported by Gazi University’s Scientific Research Projects unit (BAP) and has been completed.
01Problem
Finding a person from the air.
In search and rescue, time is critical, and a drone can cover a wide area quickly. But from altitude a person becomes a small part of the frame. Altitude, background and visibility keep changing; a person may be partly hidden or at the edge of the view.
The system does not decide. It marks candidate people on the image; confirmation belongs to the operator. The goal is to reduce the load of scanning video alone.
02System
Flight and perception, deliberately apart.
Two paths, one ground station.
Flight
- RC transmitter · RTH and auto take-off
- Pixhawk 6C · PX4
- Holybro X500 V2 frame
Edge AI
- IMX477 camera · 160° field of view
- Jetson Nano 4 GB
- YOLOv11 · TensorRT FP16 · DeepStream
Ground station
- QGroundControl · telemetry
- Operator confirmation
- RTSP client · live video with detections

Flight is flown from an RC transmitter through a Pixhawk 6C flight controller; safety functions such as return-to-home (RTH) and automatic take-off make it semi-autonomous. Image processing runs on a separate unit, a Jetson Nano. There is no command or control signal between the two: the AI only produces information and supports the operator’s decision.
03Model
Same data, two models.
Which model should run on the Jetson Nano?
On the PROJE dataset, compiled from the SARD and WiSARD datasets, YOLOv8 and YOLOv11 were compared under the same data splits and similar training procedures: pretrained weights, 640×640 input, 100 epochs, Google Colab Pro.
A data decision: informativeness over volume
WiSARD frames come at resolutions up to 4096×2160, but training runs at 640×640. Frames in which a person would shrink below what the detector can learn after that resize were deliberately excluded during curation.
- YOLOv8
- YOLOv11 · selected
| Metric | YOLOv8 | YOLOv11 | Change | |
|---|---|---|---|---|
| Precision | 0.8997 | 0.9109 | +0.0112 | |
| Recall | 0.7953 | 0.8065 | +0.0112 | |
| mAP@0.5 | 0.8433 | 0.8694 | +0.0261 | |
| mAP@0.5:0.95 | 0.4013 | 0.4481 | +0.0468 | |
| 00.51 | ||||
Detections on dataset images
Examples from both sources of the PROJE dataset: targets at the frame edge, partly visible, or very small.
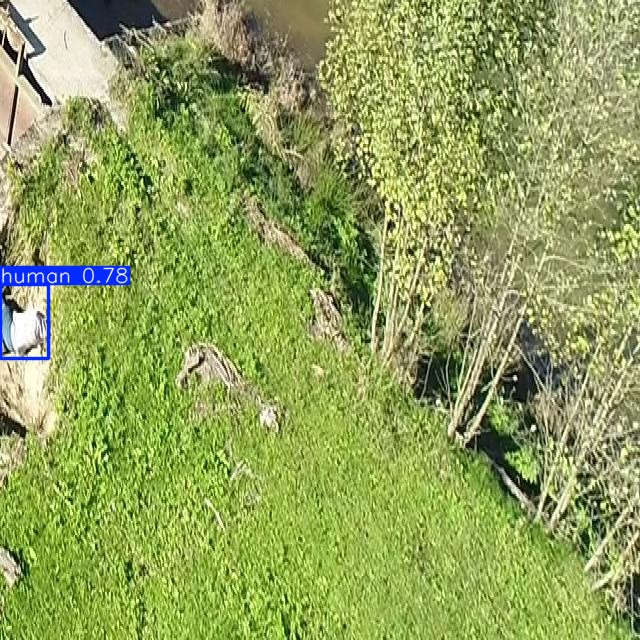
SARDA partly visible person among vegetation at the left edge of the frame (0.78).
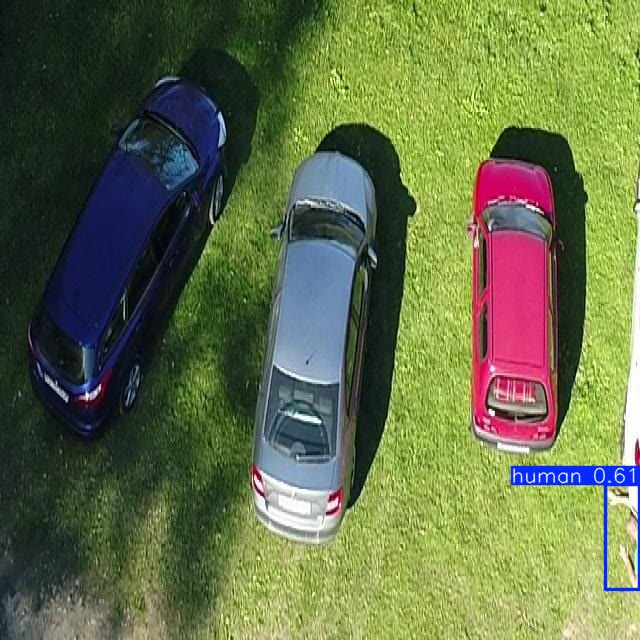
SARDA partly visible person at the right edge, next to parked cars (0.61).
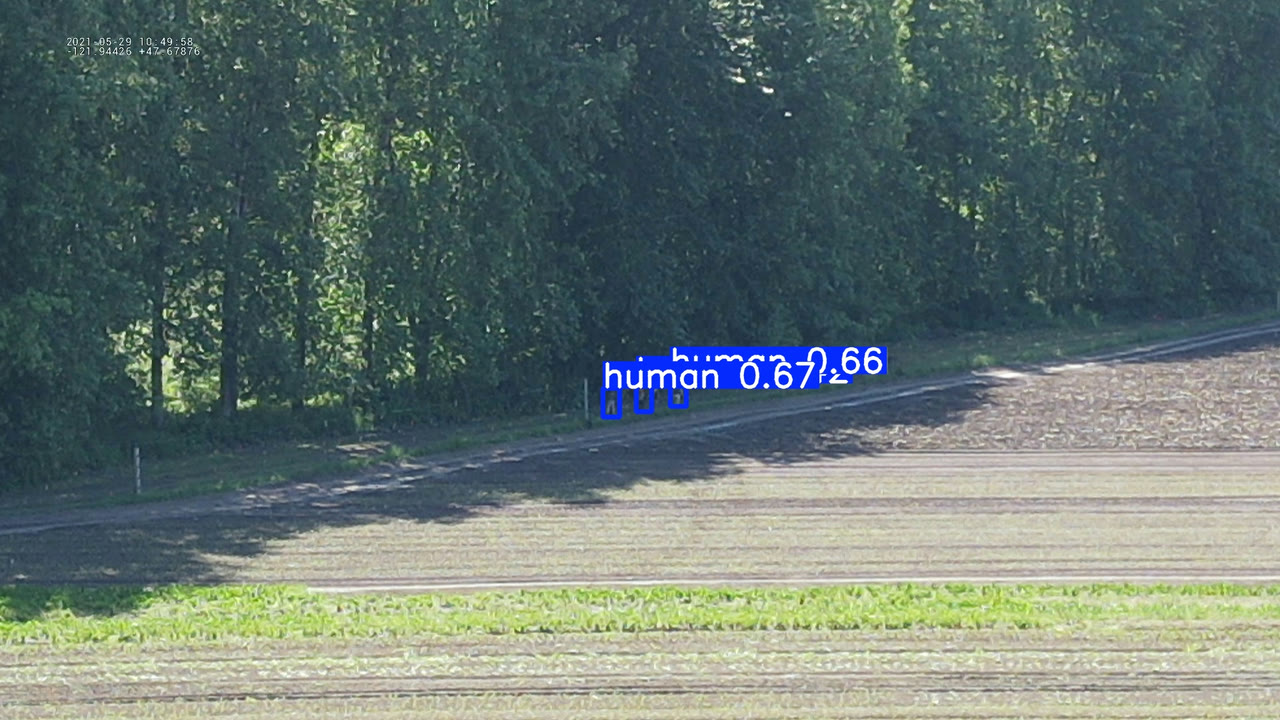
WiSARDThree people at the foot of a tree line, each a tiny part of the frame; all three are marked.


Why YOLOv11?
- 01
Better-placed boxes
The largest gain is in mAP@0.5:0.95, which covers stricter IoU thresholds: 0.4013 to 0.4481. Boxes sit more accurately on the person.
- 02
Fewer false alarms
In the confusion matrix, background mistaken for a person fell from 821 to 631.
- 03
Misses in a similar range
Missed person instances stayed close, at 1,487 and 1,562. The choice rests on precision, mAP and box placement.
YOLOv11 (with augmentation) was selected for deployment on the Jetson Nano.
04Pipeline
From frame to operator.
The model is prepared once and moved to the device; every frame is processed on the device and streamed to the operator.
Preparation · once
- TrainingPyTorch · Ultralytics · Google Colab Pro
- ONNXportable model format
- TensorRT FP16device-specific inference engine
Runtime · on the Jetson Nano, for every frame
- Camera
nvarguscamerasrcIMX477 · CSI - Batching
nvstreammuxframes grouped for inference - Inference
nvinferYOLOv11 · TensorRT FP16 - Boxes + scores
nvdsosddrawn onto the video - Encoding
nvv4l2h264enchardware H.264 - Streaming
rtph264pay · RTSPover the network - Ground stationRTSP client (e.g. VLC) · operator confirmation
05Field
Real flight, real footage.
Do the results hold up in the field?
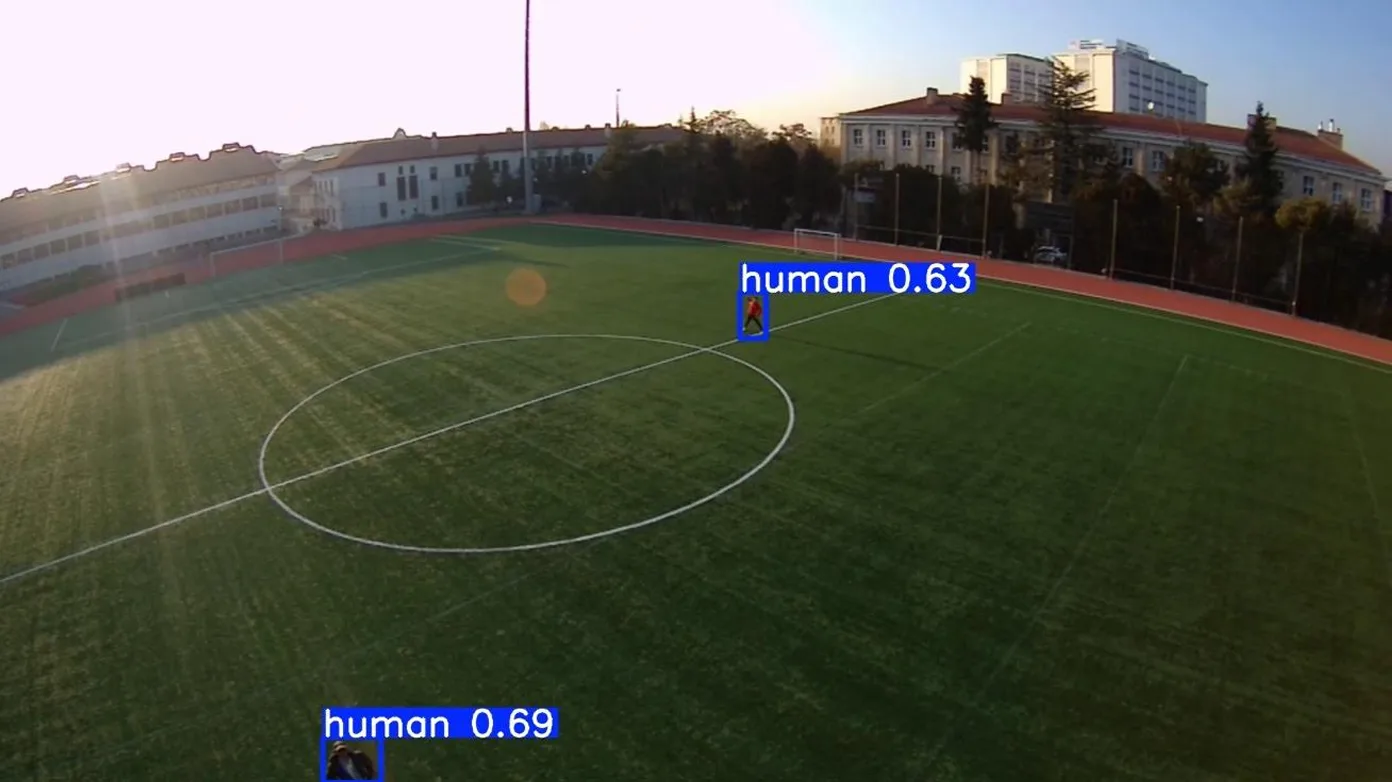
Medium altitude, wide angle: two people, one at the bottom edge of the frame (0.63 · 0.69).
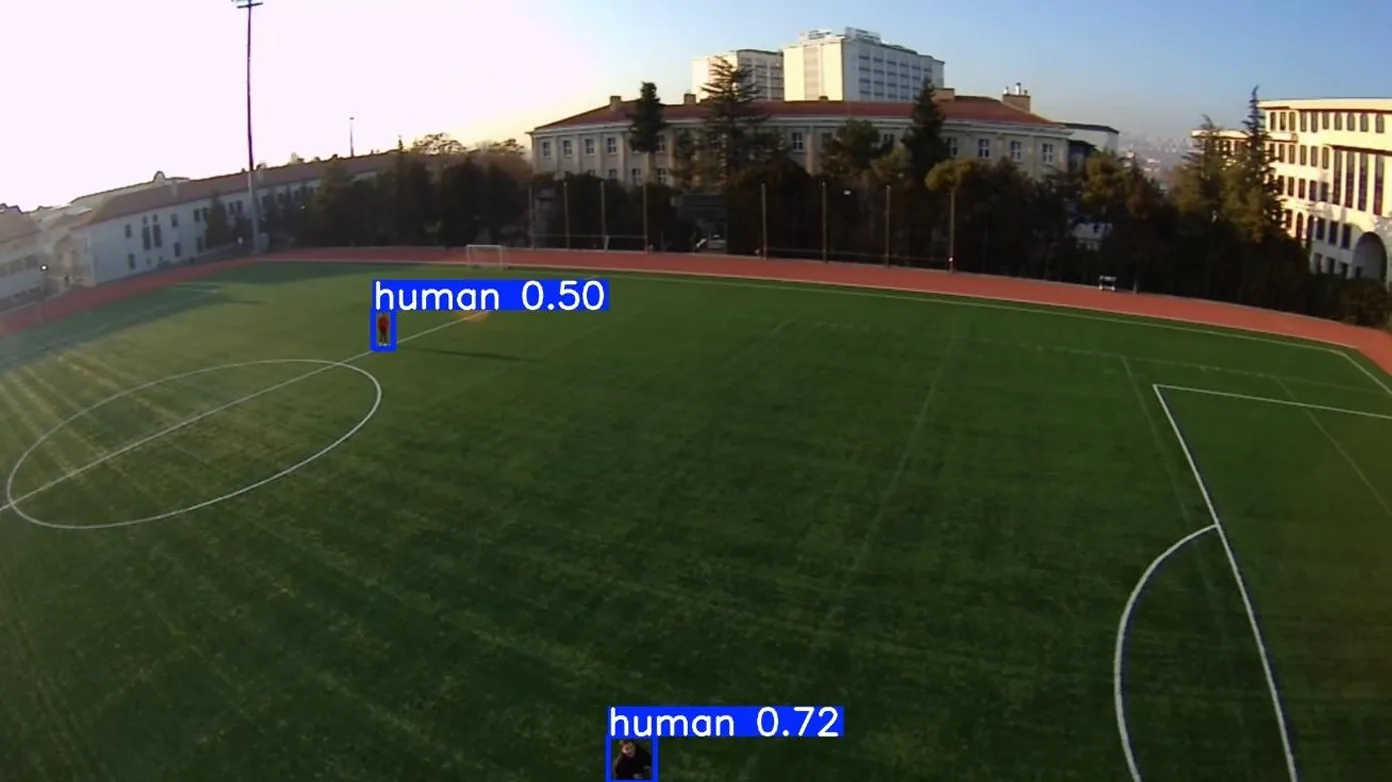
A different position and distance: two people (0.50 · 0.72).
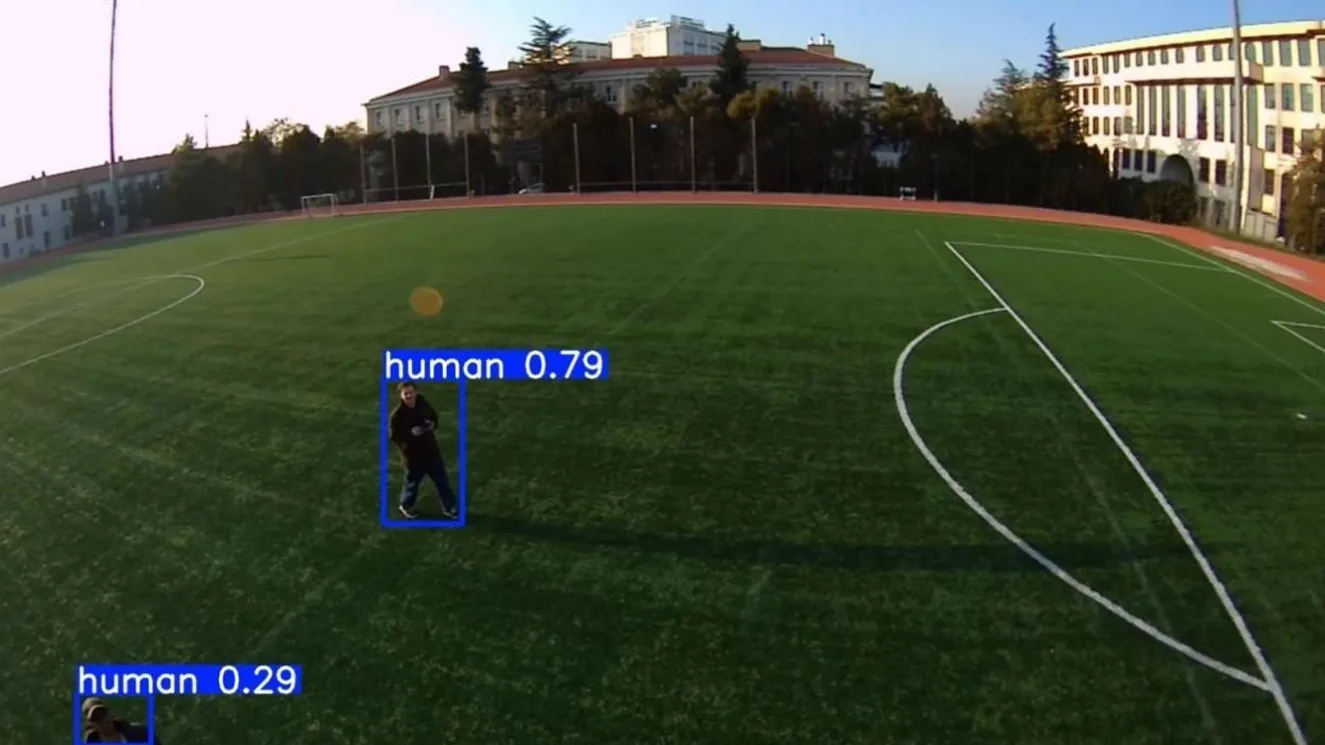
A partly visible person at the frame edge keeps a low confidence score (0.79 · 0.29).
The first field tests took place on the football pitch of Gazi University’s campus, with the required permissions. The wide, open area allowed different altitude and distance combinations to be tried safely.
Although the target’s size in the frame changed markedly, the model detected the human class consistently, including people at the edge of the frame and partly visible.
Field validation is qualitative: the footage was assessed by direct observation. No field recall, FPS or latency value was reported.
06Outcome
More than a model: a working system.
- 01
From data to model
Data compiled from two public datasets; two architectures compared under the same conditions, and a reasoned model choice.
- 02
From model to device
Inference on a Jetson Nano with ONNX and TensorRT FP16, inside a DeepStream pipeline.
- 03
From device to operator
Annotated video streamed to the ground station over RTSP; a perception path kept separate from flight.
- 04
From the lab to the field
Qualitative field validation on campus with real flight footage.
Bachelor’s thesis · Gazi University Faculty of Technology · supported by Gazi University BAP · 2026 · joint work with Mohamedou Mohamedhen Vall